Hermes Local AI & On-Premises Private LLM Infrastructure
Air-gapped, zero-data-leakage local AI deployment running Nous Hermes 3 and Llama 3 on private GPU hardware with high throughput.
Zero outbound network traffic; fully compliant with air-gapped security
Optimized 4-bit and 8-bit quantized execution with vLLM PagedAttention
Eliminated per-token API charges for high-volume internal document analysis
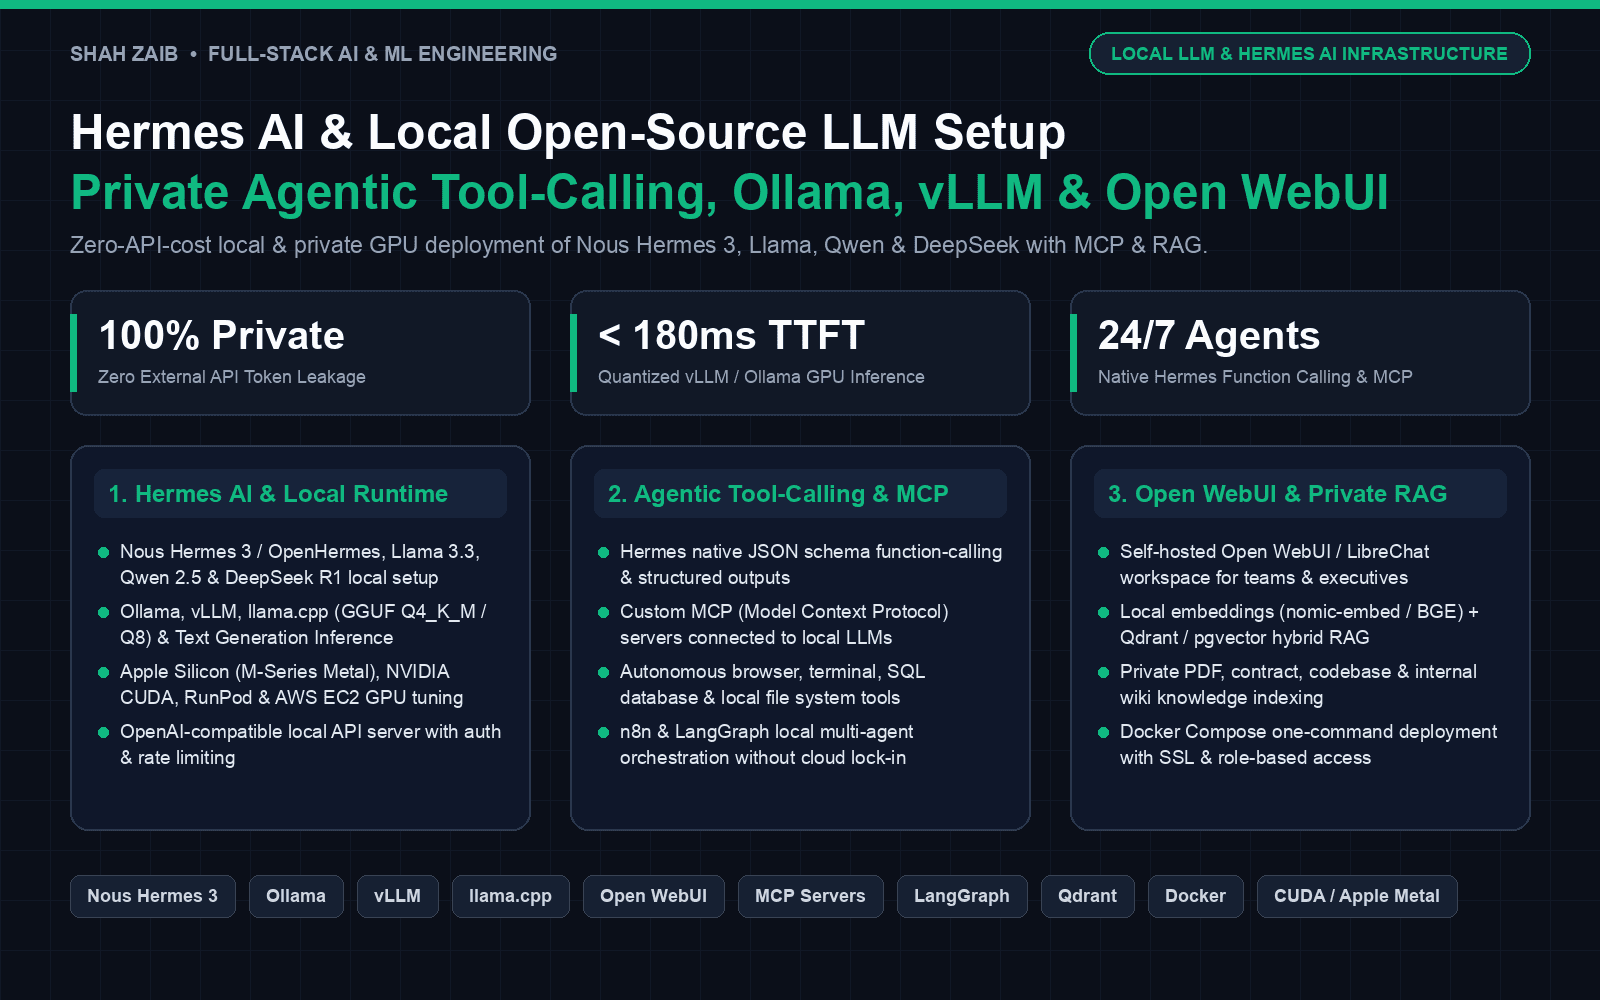
Project Architecture & Objectives
Key Capabilities Delivered
Configured local GPU acceleration (NVIDIA CUDA / Apple Metal MPS) with vLLM and Ollama runtimes
Built OpenAI-compatible API reverse proxy in FastAPI enabling drop-in replacement for existing software
Created local RAG knowledge base utilizing Ollama embeddings and local pgvector database
Set up automated model quantization (GGUF, AWQ, FP8) to balance token throughput and memory footprint
Packaged complete local AI stack into reproducible Docker Compose manifests with monitoring scripts
Engineering Challenges & Solutions
Critical architectural hurdles solved to deliver performance, security, and scale.
Memory Constraints on Large Context Windows
Running 32k+ context models on local hardware leads to out-of-memory errors and severely throttled token speeds.
Utilized AWQ quantization combined with vLLM PagedAttention and continuous batching to maximize VRAM efficiency.
Visual Systems & User Experience
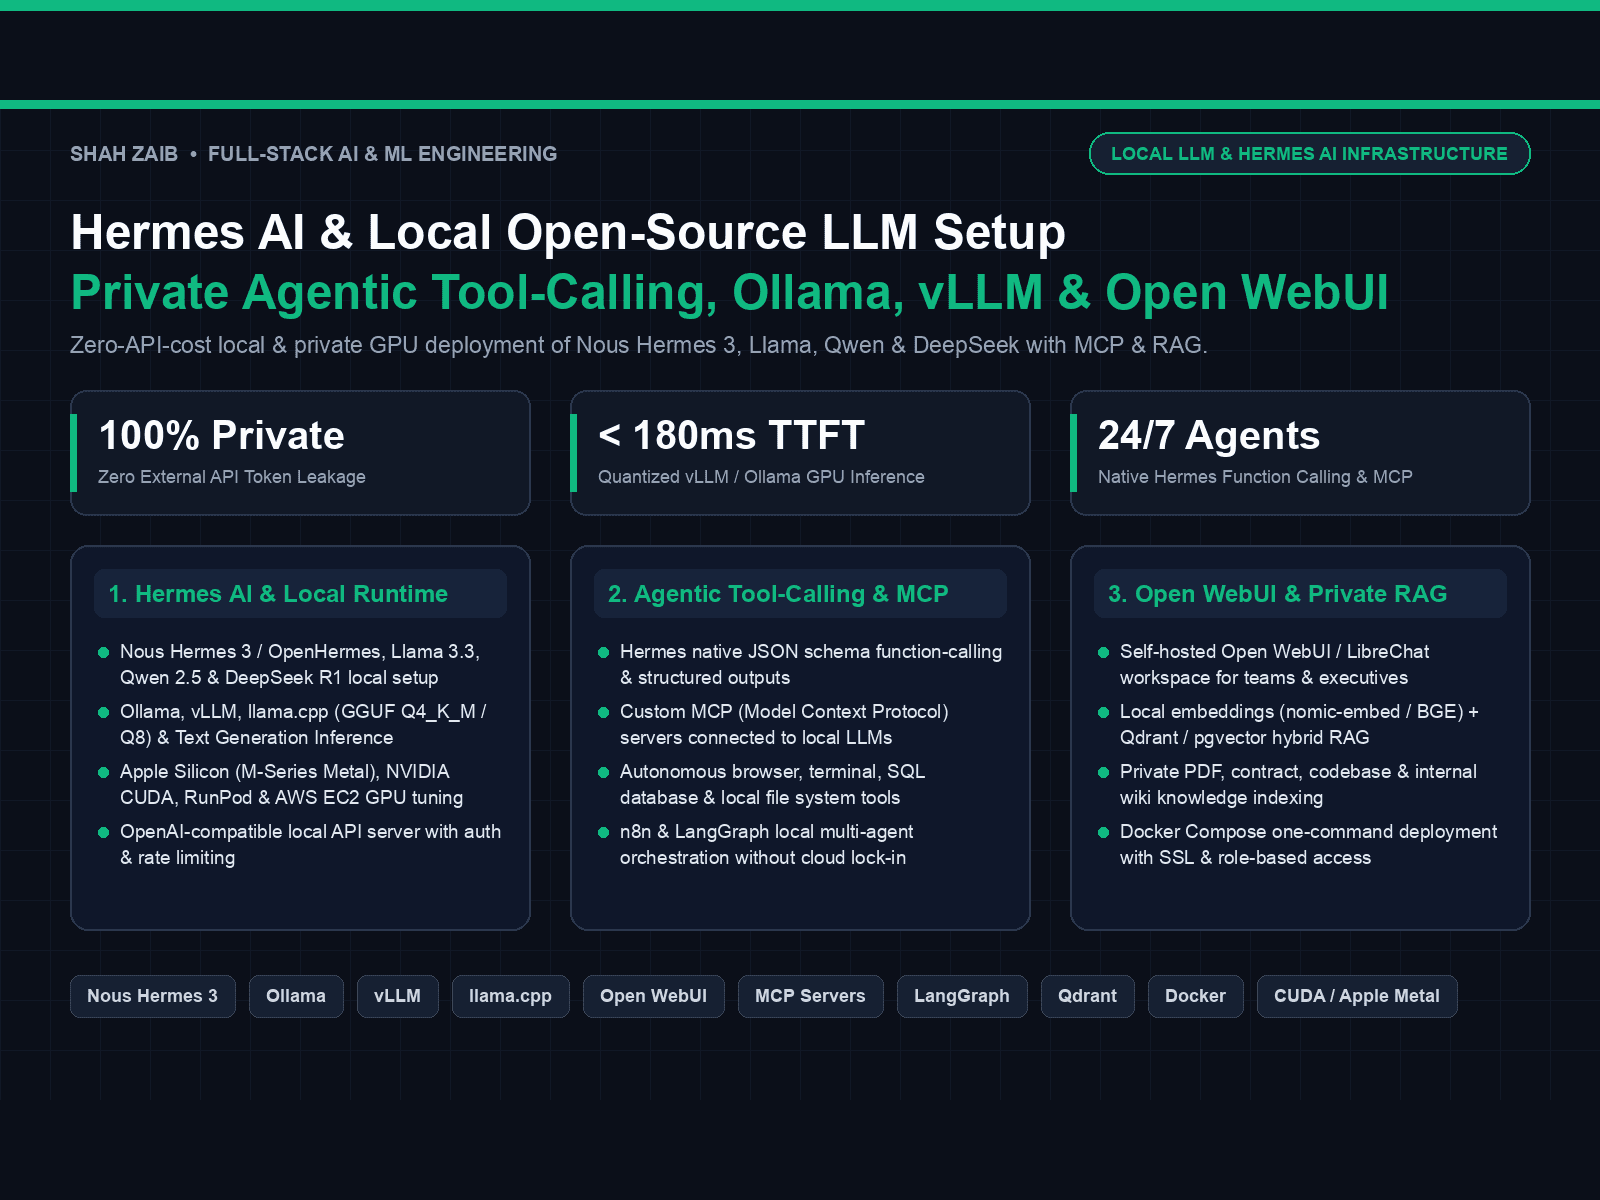
Technologies & Infrastructure
Have a Complex AI or Full-Stack System in Mind?
Whether you need custom MCP servers, RAG pipelines, autonomous n8n workflows, or scalable SaaS backends, let's build it right the first time.