Domain LLM Fine-Tuning & Curated Data Preparation Pipeline
Automated ETL pipeline that scrapes, sanitizes, dedupes, and synthesizes domain-specific datasets for LoRA / QLoRA model fine-tuning.
Outperformed generic GPT-4o on specialized industry terminology and formatting
Automated synthesis and deduplication pipeline producing clean training data
Smaller 8B fine-tuned model replaced expensive multi-shot prompt injections
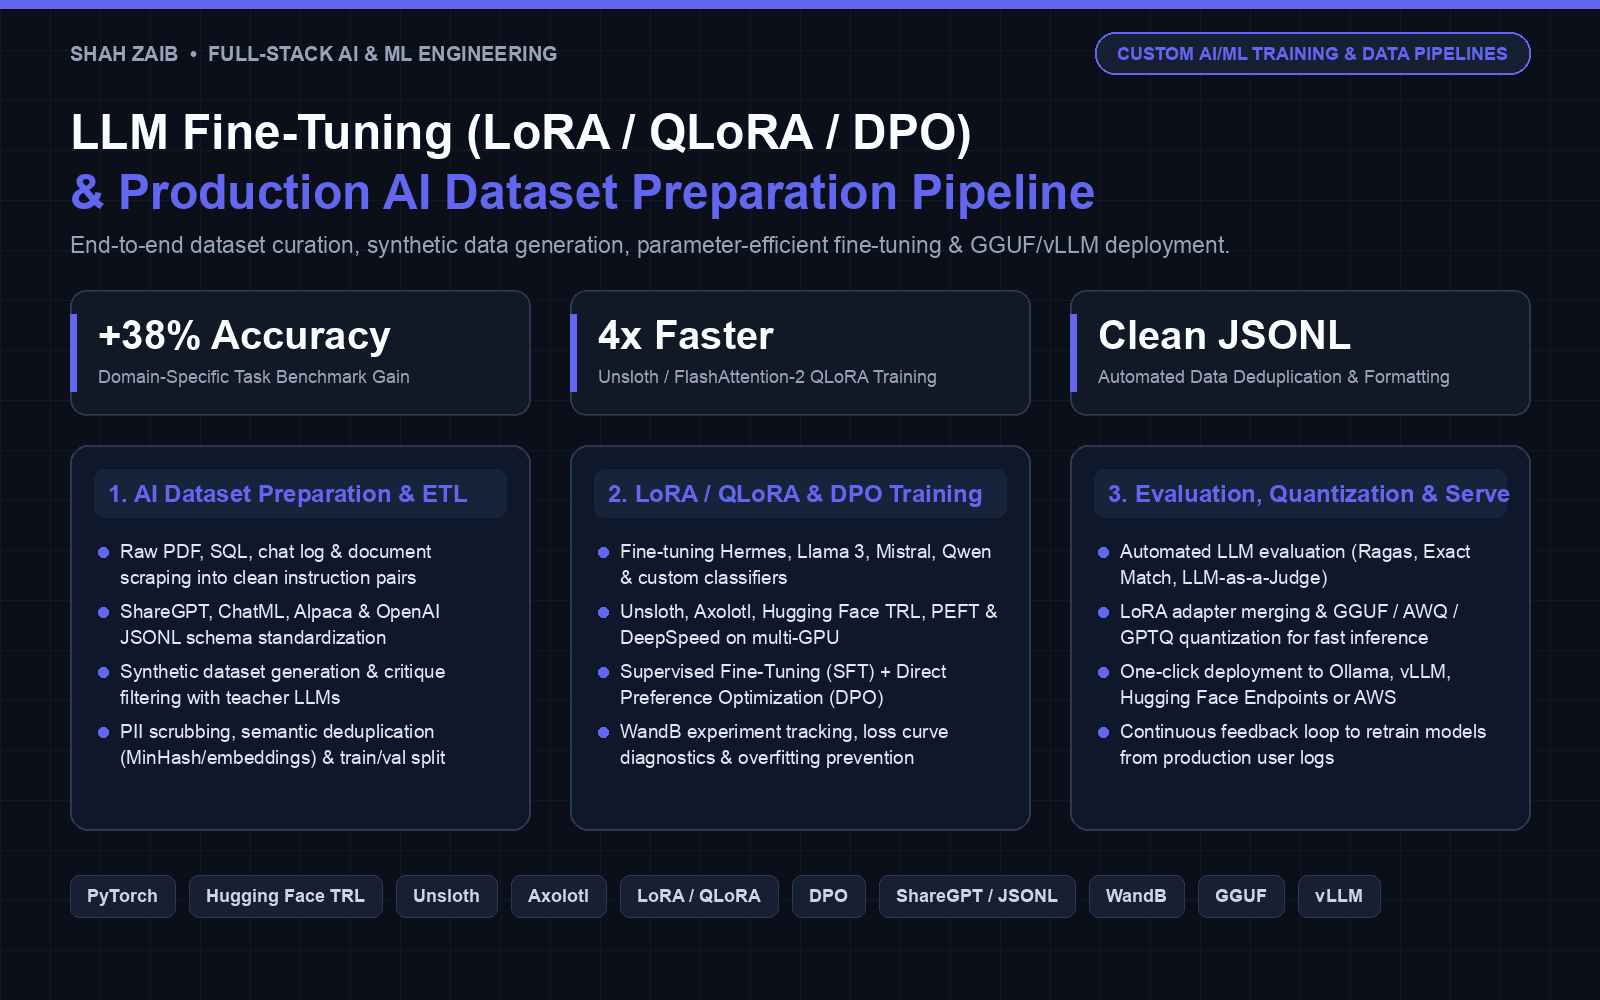
Project Architecture & Objectives
Key Capabilities Delivered
Developed Python data ingestion pipelines using pandas and Polars to clean and deduplicate raw corporate documentation
Built automated synthetic data generator with self-consistency filtering to create high-quality instruction datasets
Configured parameter-efficient fine-tuning (PEFT / LoRA / QLoRA) on multi-GPU nodes with Hugging Face Transformers
Tracked training loss, gradient norms, and evaluation metrics using Weights & Biases dashboards
Engineering Challenges & Solutions
Critical architectural hurdles solved to deliver performance, security, and scale.
Catastrophic Forgetting & Format Hallucinations
Fine-tuning base models on domain data frequently degrades their general reasoning and conversational formatting.
Mixed 20% general instruction data with domain samples and applied strict EOS token masking during loss calculation.
Visual Systems & User Experience
Technologies & Infrastructure
Have a Complex AI or Full-Stack System in Mind?
Whether you need custom MCP servers, RAG pipelines, autonomous n8n workflows, or scalable SaaS backends, let's build it right the first time.