Voxento — Real-Time WebRTC Audio, Voice AI & Transcription Engine
Ultra-low-latency real-time voice communication platform featuring instant AI transcription, speaker diarization, and interactive learning modules.
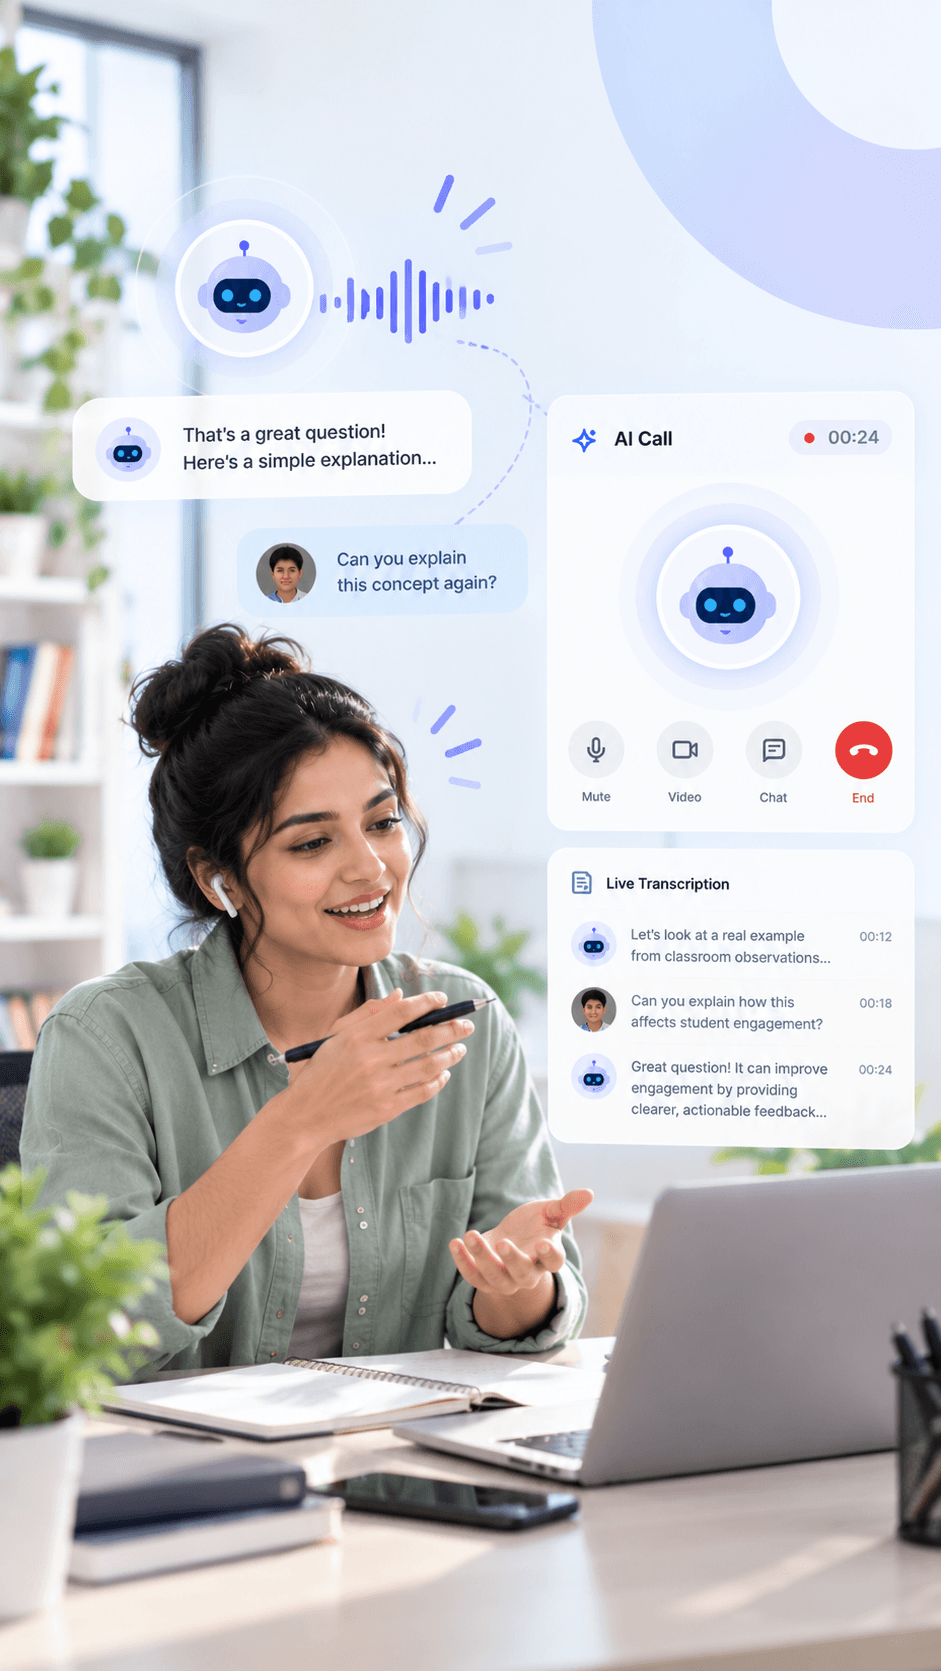
Real-time bi-directional audio streaming and instant transcription
Custom fine-tuned Whisper model handles varied international accents
Scalable audio streaming architecture with zero packet degradation
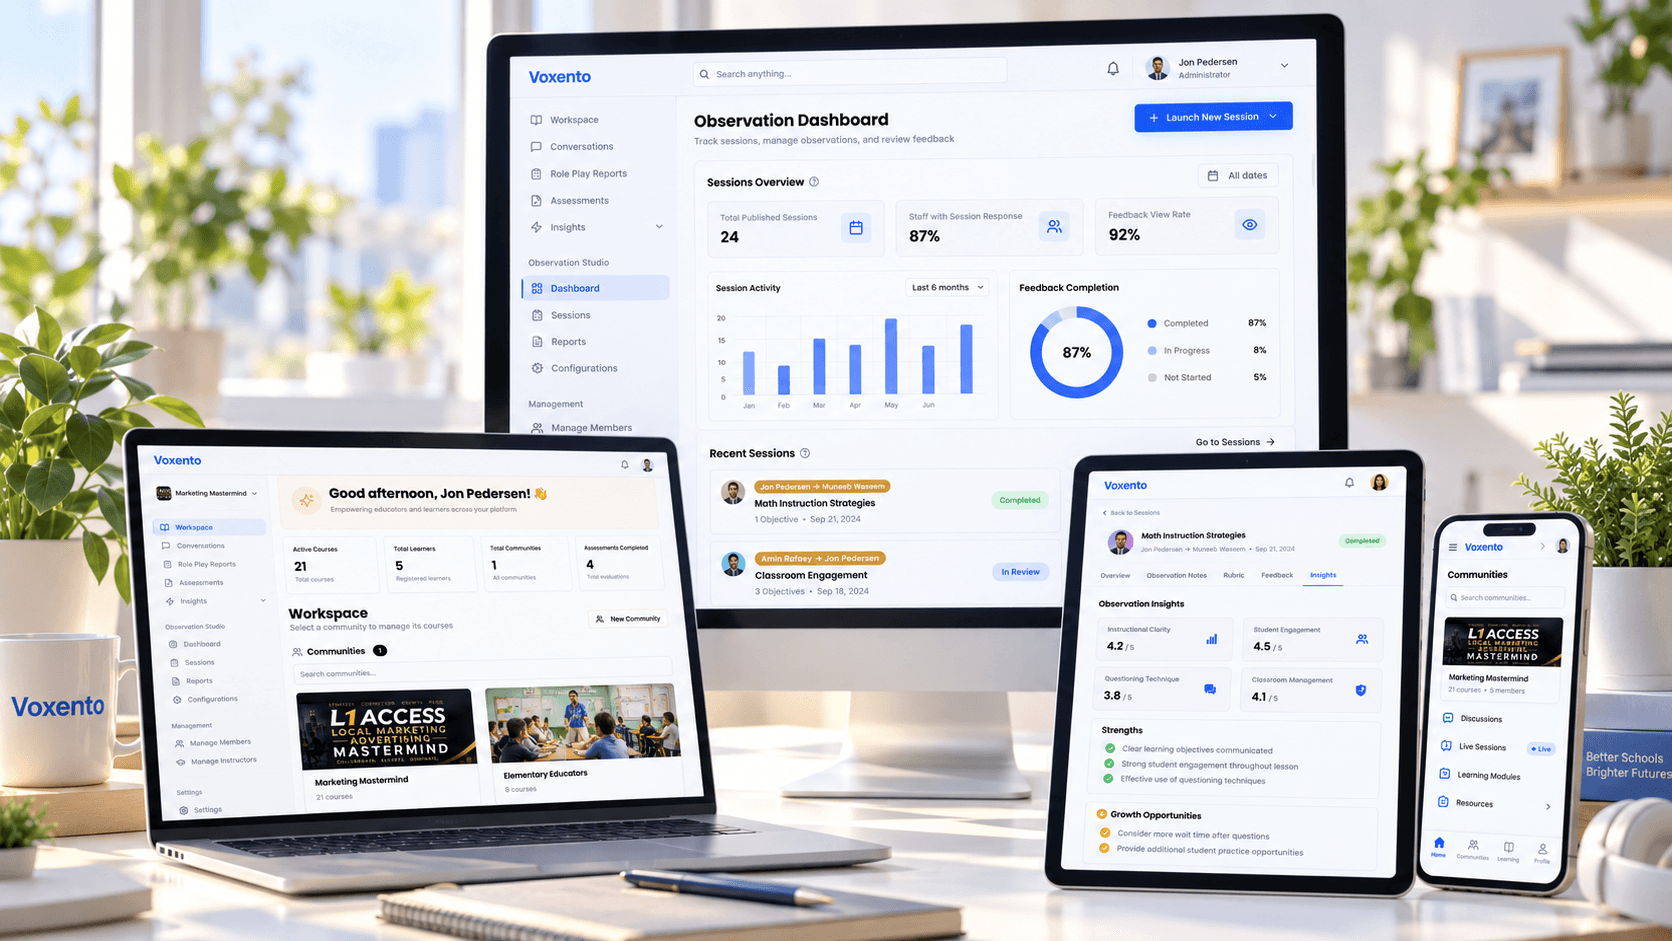
Project Architecture & Objectives
Key Capabilities Delivered
Built resilient WebRTC audio streaming pipelines supporting peer-to-peer and SFU room topologies
Integrated OpenAI Whisper API with chunked streaming buffers for live real-time captioning without audible delay
Engineered speech synthesis pipelines using ElevenLabs with natural voice inflections for automated interactive coaches
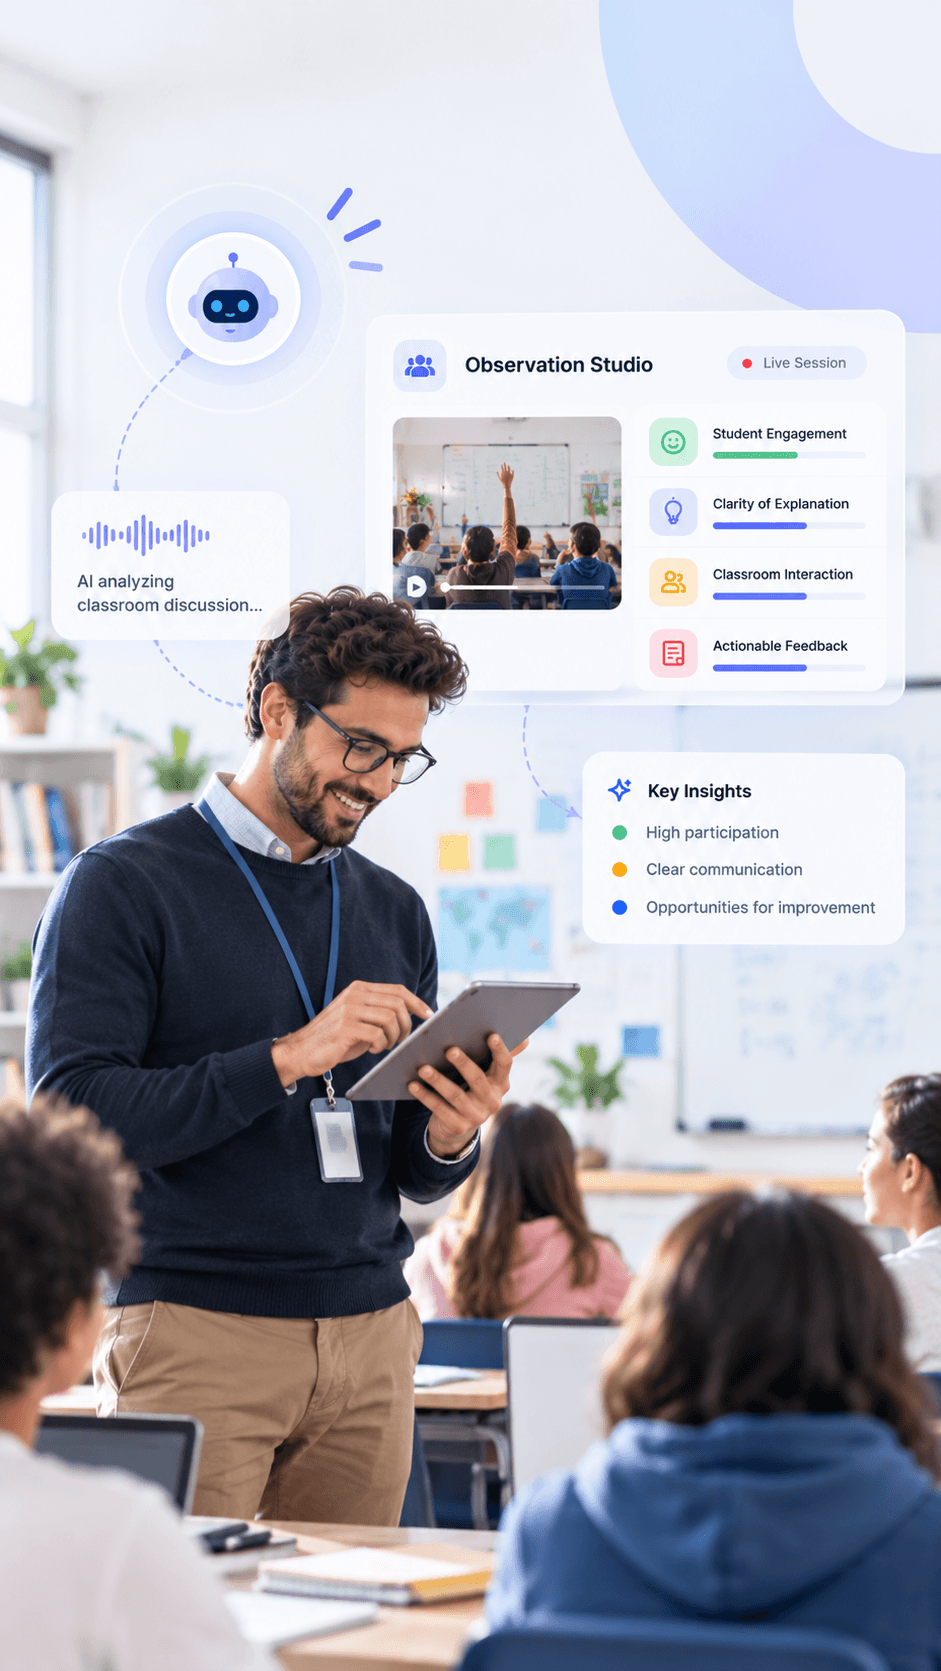
Constructed observation studio UI allowing coaches to review call transcripts, highlight key speaking moments, and export notes
Optimized media delivery infrastructure across AWS CloudFront and S3 for persistent call recordings
Engineering Challenges & Solutions
Critical architectural hurdles solved to deliver performance, security, and scale.
Audio Packet Jitter and Chunked Transcription Sync
Transcribing live streams in chunks often results in clipped words at chunk boundaries and transcription drift.
Built a rolling sliding-window audio buffer with Voice Activity Detection (VAD) that cuts audio chunks only during natural conversational pauses.
Bidirectional Low Latency Voice Synthesis
Returning synthesized speech back to caller rooms within conversation cadence required sub-500ms pipeline execution.
Streamed raw audio chunks over WebSockets directly to the audio context buffer while streaming synthesis from ElevenLabs.
Visual Systems & User Experience
Technologies & Infrastructure
Have a Complex AI or Full-Stack System in Mind?
Whether you need custom MCP servers, RAG pipelines, autonomous n8n workflows, or scalable SaaS backends, let's build it right the first time.